Voice AI Copilot
Voice AI copilot with speech recognition, LLM tool calling & Web Audio DSP.
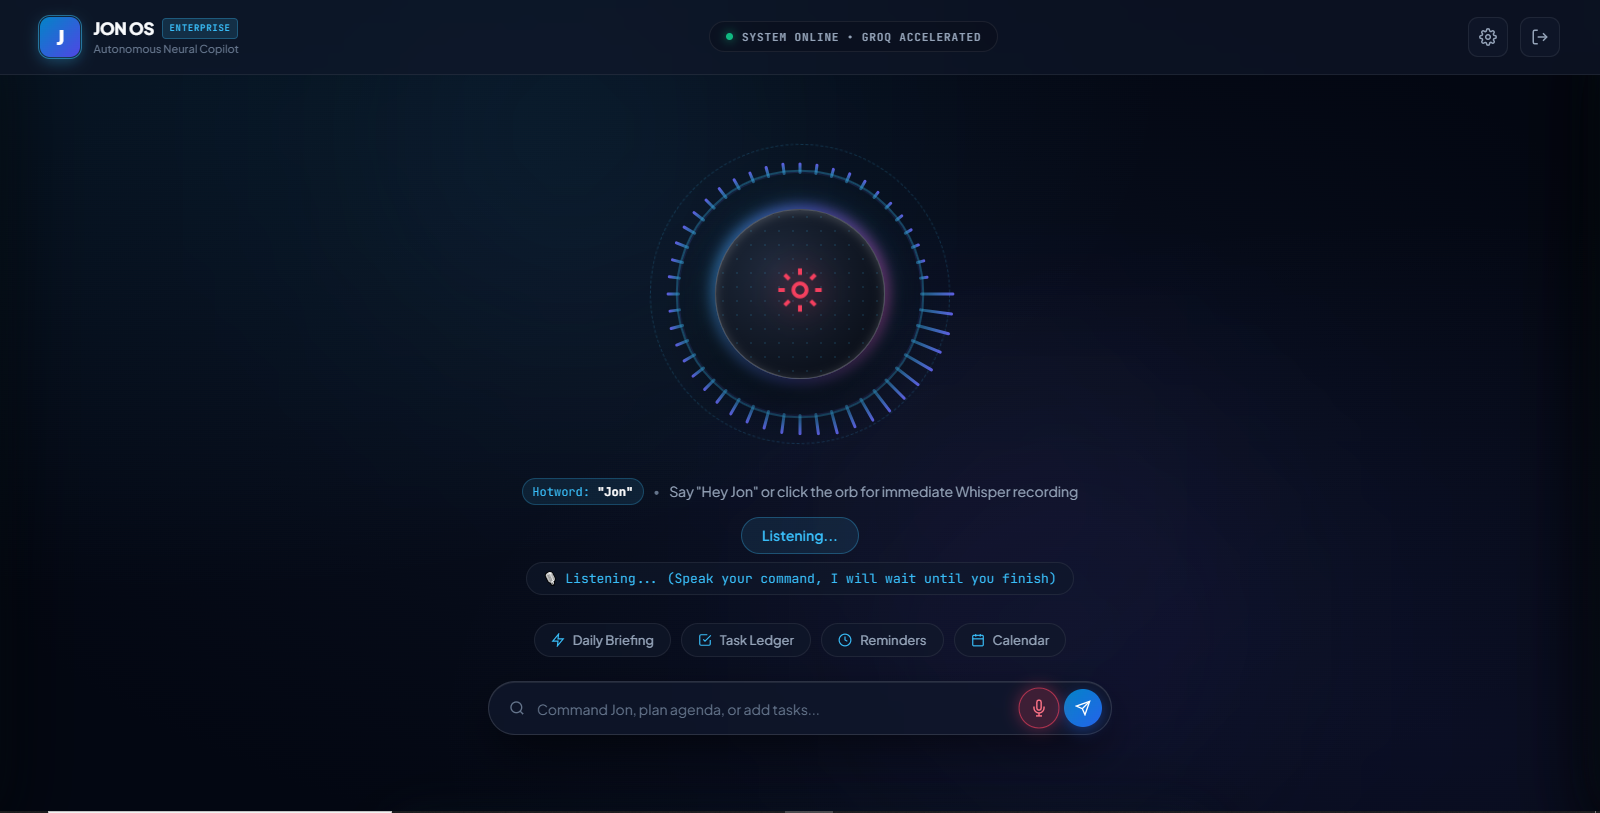
Central voice interface with real-time audio visualizer canvas, hotword status, and command bar
System Overview & Engineering Longevity
A browser-based voice assistant engineered for hands-free task management and low-latency interaction. Built with modern JavaScript ES Modules, Vite, and cloud-accelerated AI inference, the application couples browser hotword listening with speech-to-text transcription. Ambient audio is processed via Web Audio API AnalyserNode RMS energy calculation to detect conversational pauses naturally. Spoken commands are interpreted by an LLM into structured JSON tool execution payloads for Firestore task management, reminder scheduling, and daily agenda briefings, visualised in an interactive HUD with a radial audio frequency visualizer.
Key Engineering Highlights
Architected with clean domain separation, strict TypeScript contracts, and automated telemetry logging.
Cloud STT
Cloud speech-to-text inference
Intent Parsing
Structured tool schema extraction
Silence Detection
Dynamic RMS energy monitoring
Hotword Listening
In-browser wake-word detection
Audio Visualizer
Real-time frequency spectrum rendering
Cloud Database
User-scoped task and reminder sync
End-to-End System Data Flow
How user inputs, computer vision pipelines, and transaction protocols flow across the stack.
Hotword Listening
In-browser Web Speech listener scans ambient audio for wake words ("Jon", "Hey Jon") without continuous server calls.
Audio DSP & Silence Detection
Web Audio API AnalyserNode tracks live RMS amplitude; records microphone input until conversational silence is reached.
Cloud Speech-to-Text
Captured audio is sent to cloud Whisper inference, returning structured speech transcription.
LLM Intent Parsing
Transcript is evaluated by the LLM against defined tool schemas, resolving intent into validated JSON actions.
Firestore Mutation & Voice Feedback
Action executes against Firestore (task/reminder), an acoustic cue plays, and synthesized speech confirms the result.
Reactive State Update
Canvas visualizer resets to idle state, task drawer updates via Firestore snapshot, and HUD updates status.
System Capabilities & 3+ Functional Modules
Voice Pipeline & Hotword Listener
Acoustic intake engine bridging in-browser wake-word detection into cloud transcription. Monitors for wake utterances and captures microphone audio for transcription.
Task Ledger & Reminders Engine
Firebase Firestore persistence layer providing reactive state synchronization for user tasks, agenda items, and scheduled notifications.
Interactive HUD & Audio Canvas
Modern interface featuring multi-layered backdrop blur filters, glowing light fields, and canvas-rendered audio frequency visualizers.
Key Engineering Bottlenecks & Solutions
Conversational Truncation in Voice Capture
Fixed-length audio recording cuts off slower speakers. Solved by implementing continuous Web Audio API RMS energy tracking that extends recording while vocal frequencies remain active, finalizing only after sustained silence.
End-to-End Latency from Voice to Spoken Output
Multi-hop pipelines (Wake -> STT -> LLM -> DB -> TTS) can introduce noticeable latency. Minimized roundtrip delay by leveraging fast cloud inference and executing database mutations concurrently while synthesis prepares audio.
Structured Tool Calling from Conversational Voice
Voice commands frequently contain ambiguous phrasing or informal time references. Used structured tool schemas and prompt grounding to enforce clean JSON payload formatting with schema validation and fallback handling.
Real-Time Canvas Audio Visualization Performance
Rendering frequency bins in real time alongside CSS blur effects can impact browser performance. Optimized the animation loop using requestAnimationFrame with pre-allocated TypedArray buffers (Uint8Array) on an isolated canvas layer.
GardenMate Ecosystem
Custom Vision Transformer AI + Viro AR mobile platform with 12+ modules.